Open sourcePortable charactersRuns on your GPU
The open .char format for portable characters
Build a character once and it stays itself. Same face, body, clothes and voice in every image and video, carried in a portable .char file you can load in OmniChar, ComfyUI or through the API.
Install it on your own machineView on GitHub
Works with
- MiniMax H3
- Flux
- Z-Image
- Krea
- LTX
- Qwen 2.1
USE CASES
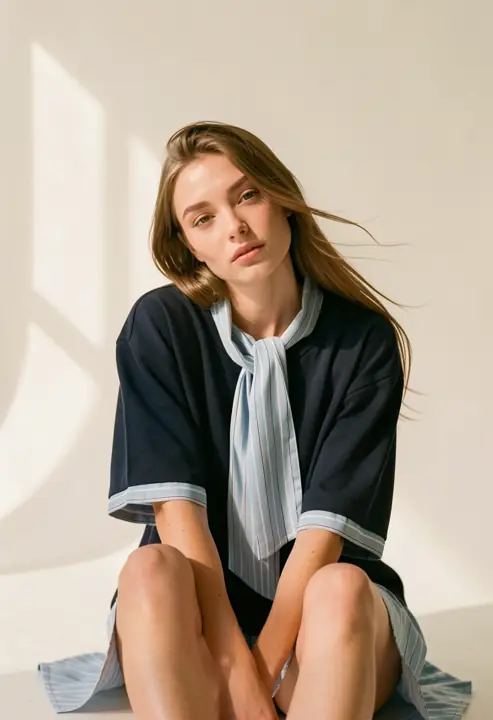
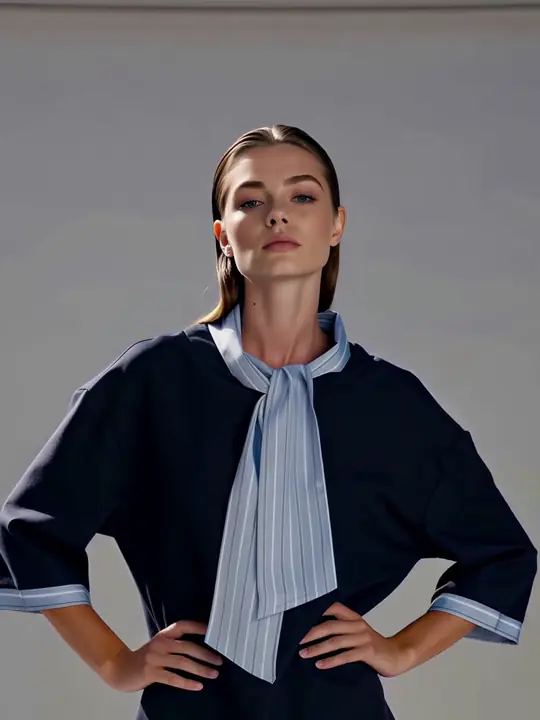
One .char file carries the face, body, clothes and voice. Build it once and use it in any of these.
 SIA.CHAR
 ARON.CHAR
Inputs → Output
Use case 01 / 04
Consent that travels with the character
Build a character from a real person, with their consent. The license lives inside the .char file, OmniChar checks it before every generation, and the owner can revoke it at any time.
- 01Build with consent
- 02License each use
- 03Verify anywhere
- 04Track and revoke
- Face
- Body
- Clothes
- Voice
- License
- Owner
- Omnicast Talents
- Scope
- Online ads · EU · Jan to Jun 2027
- Status
- Valid, not revoked
The same .char works everywhere
Start wherever you work today. Move between them without rebuilding the character.
 cloud.omnichar.org
Build a character from 1-3 photos and generate images and video right away. Nothing to install.
- 300 free credits
- Image + video
- Up to 4K
WHAT PEOPLE ARE SAYING
“This is the part of open source you can’t fake. Someone wanted a tool that didn’t exist, built it on us, and gave it to everyone.”
 Robin HuangCofounder, ComfyUI
Community characters
Browse →Character of the week
Nov 2 - Nov 8 · new pick every Monday
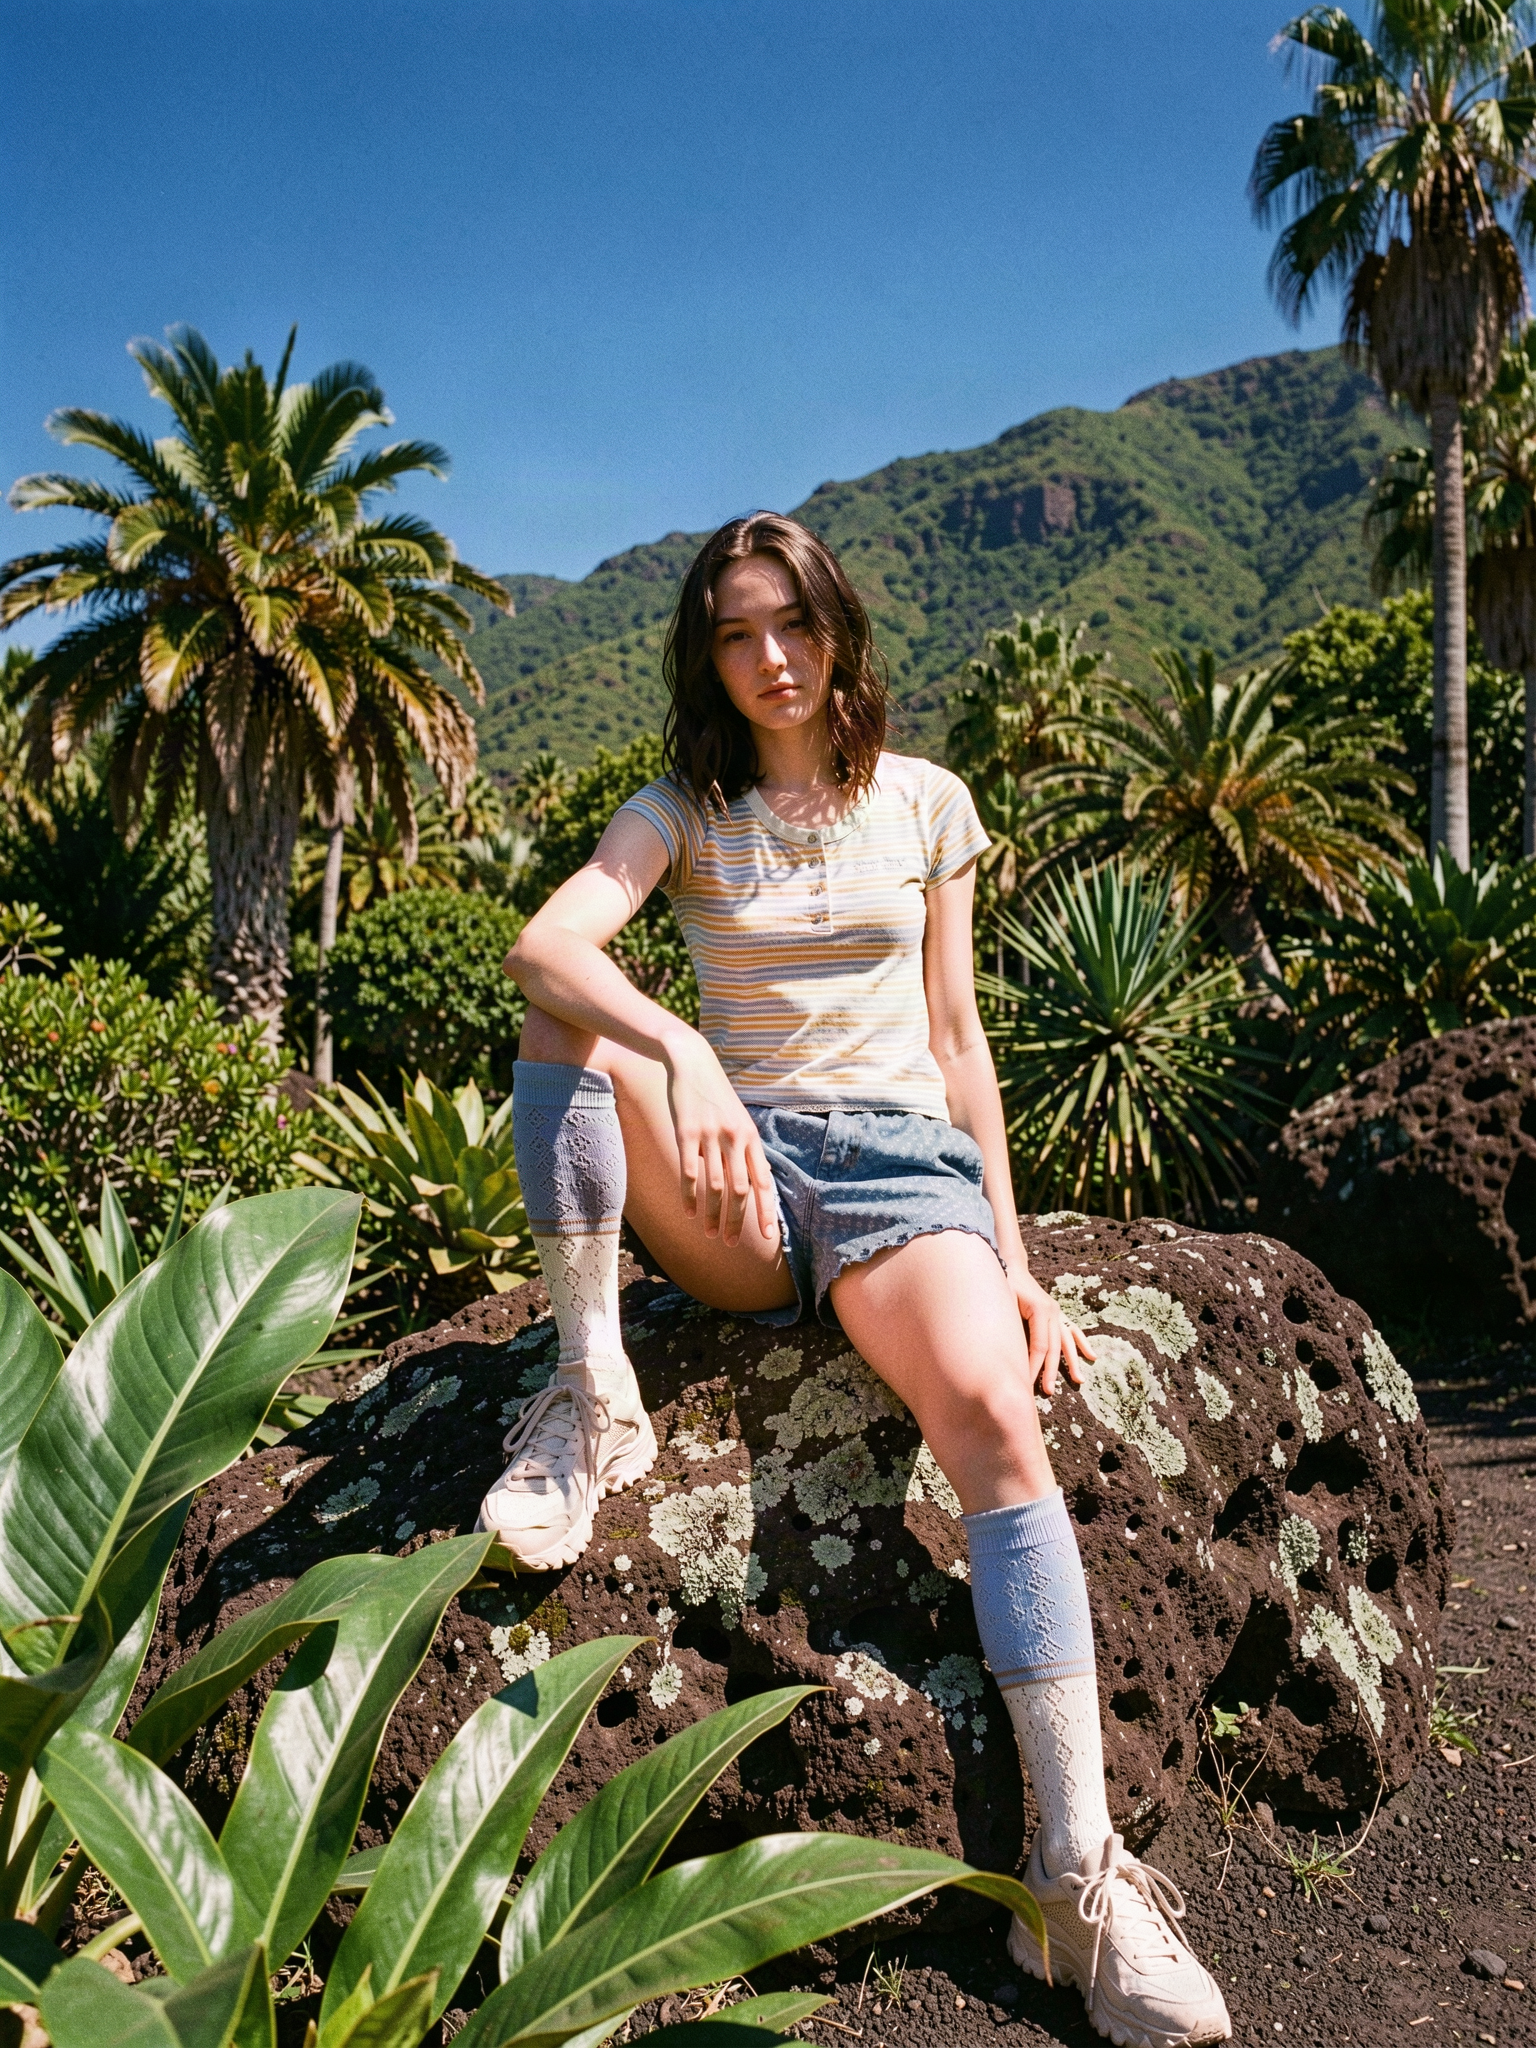
sia
Free@imprsnst1 month ago
a 22 year old girl, model like looks, fair skin
- 258
- views
- 22
- downloads
- 0
- likes
- Works with
- FLUX.2 Klein, MiniMax H3
- Size
- 15.1 MB
 +4
a 19 year old girl, petite body, fair skin
Workflows
Import a graph and generate on the first run
Each one opens on your canvas with its nodes wired and the models it needs listed. Swap the inputs and run it.
Minimax H3: Consistent face, body & cloths via reference identity
Guild your character with consistent face, body & cloths. Add upto 9 reference image & port these into face, body &…
Generate consistent characters via reference identity with Minimax H3
Unified consistent character(.char) across videos with Minimax-H3. Drop 2-5 image, describe your character & get the…
Virtual try on with portable consistent character: Flux2 Klein 9B & 4B
Consistent character generation with Flux2 klein9B & 4B models, no training required. Drop 2-5 image, describe your…
Krea 2: Generate consistent images with unified .char model
Generate consistent images with unified character model .char.
Character consistency
Portable characters, across models
A character (.char) is a small file. Your photos are standardised once and stored with an SFace face signature and a DINOv2 subject signature. FLUX.2 reads those references directly, with nothing to train. Krea 2 has no reference channel, so it takes a LoRA trained from the same photos. One file carries both.
The references
Generated from them, one prompt each
City street, low angle
Cafe window, overcast
Lakeside, open water
Park, open shade
Street, mid-stride
Office, window light
One character, six prompts, no images re-attached. On FLUX.2 the references ride in its own multi-reference channel, so there is nothing to train and nothing extra to install.
Built for iteration
The canvas underneath it
Characters are the reason to be here. The canvas is what makes them cheap to get right: every shot keeps every take, the project saves itself as you go, and every image carries the graph that made it.
A · Takes
Regenerating doesn't destroy
Every render becomes a take under a shot. Compare them, promote one, roll back. The graph stays the same size no matter how many attempts you burned getting there.
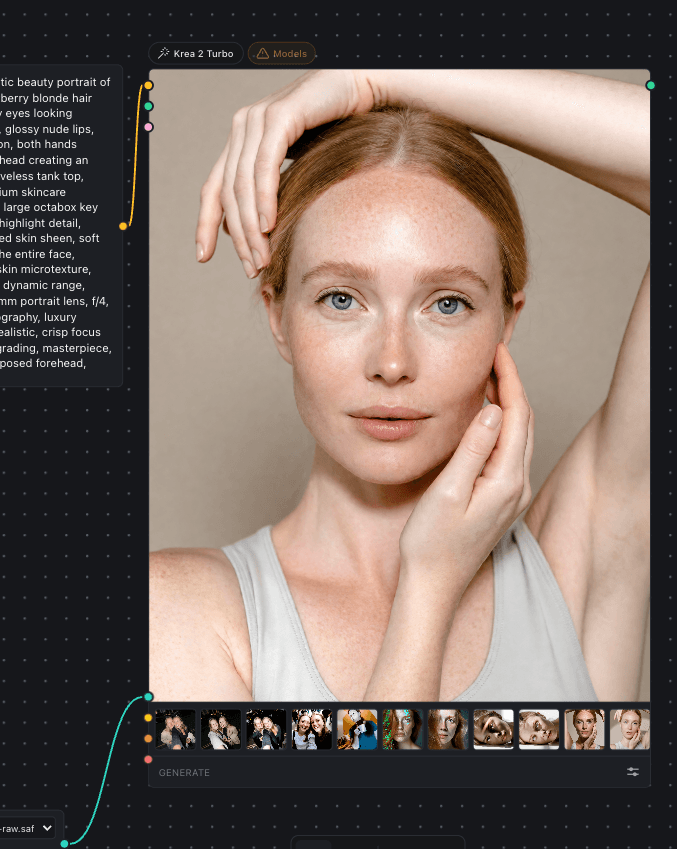
B · Sequences
Shots in order, not scattered
Every shot wires into the next, so the links are the sequence. Follow them across the canvas and you can read the whole thing in order: what feeds what, and which take carried forward.
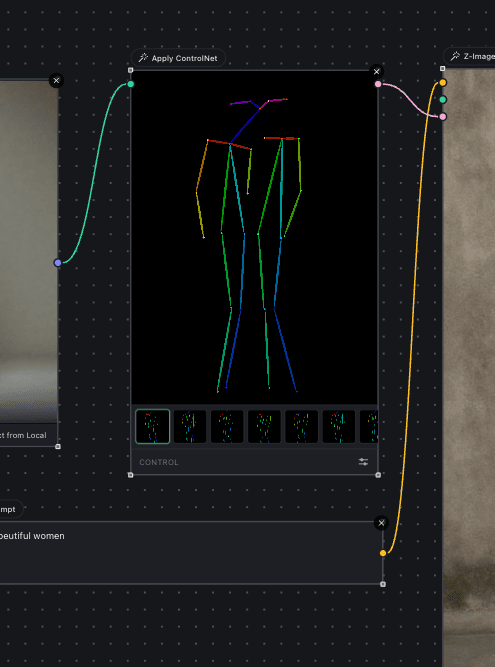
C · One process
The engine lives in the app
Our own diffusion engine runs in-process. We got tired of babysitting a second server and of backends drifting out of step with the editor, so we brought it inside.
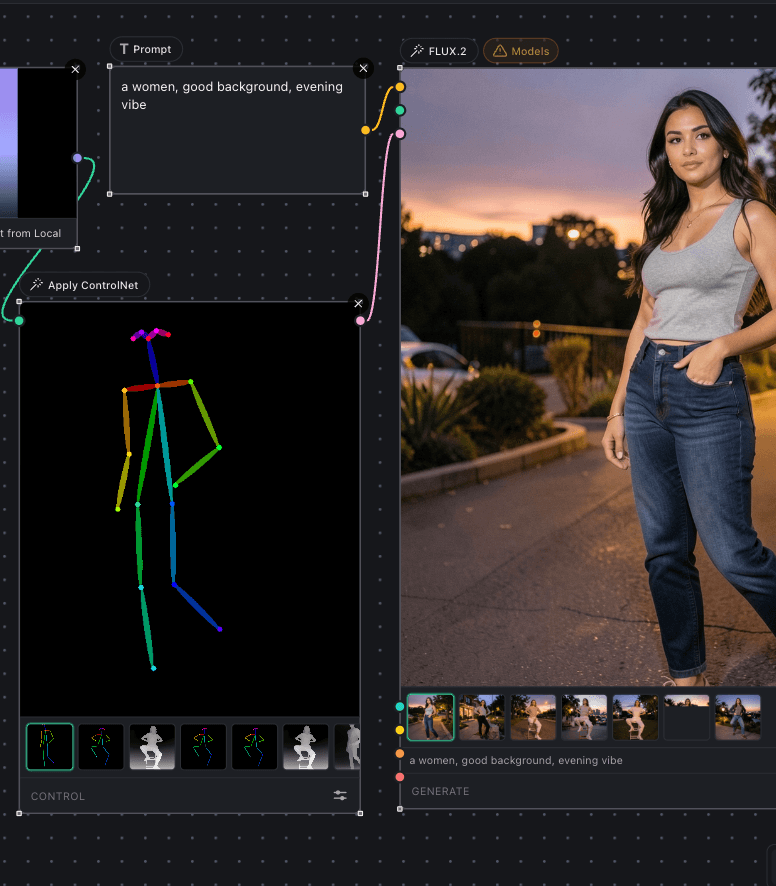
Video training, locally
Train clips on your own GPU
Most LoRAs learn a style. A Control LoRA learns a transform: you give it pairs of clips, a reference and the result you want from it, and it learns to carry one into the other. Train it on your own GPU with LTX-2.5, then drive a generation from an edge map, a depth pass or a pose track.
Pairs from Lightricks' Canny Control dataset, where each reference is an edge map of its target. Your own pairs work the same way, and the two halves need to line up frame for frame. Training an LTX-2.5 LoRA.
Trained with OmniChar
Krea 2 LoRA for realistic skin texture
Our first published LoRA brings back real pores, fine hair, and natural texture across skin tones, ages, and lighting. Free to download, with the dataset it trained on.
- Base: Krea 2 RAW, carries over to Turbo
- Rank 16, full scope (attention + feed-forward)
- 1024px, 1500 steps, learning rate 1e-4
- 26 image and caption pairs
- Trigger: inline-skin-lora
- Downloads
- 3k
- Likes
- 85
Click to zoom
Local generation
Generate locally, built in
Inline Core is a from-scratch generation engine built into OmniChar. No account, no external server, no cloud. Drop a Z-Image Turbo, FLUX.2 or Krea 2 node, wire a prompt, and hit Run. That is one node, with no loader, sampler, or VAE wiring, generating on your own GPU. Krea 2 ships as two models that work together: Turbo for fast 8-step images and RAW for maximum quality, and any LoRA you train applies to both. Video gets a section of its own below. Core owns the whole backend: it serves the web UI, runs the models, keeps the project database, and drives the timeline, all as a single Python process. Add a LoRA loader node to bring your own LoRA models.
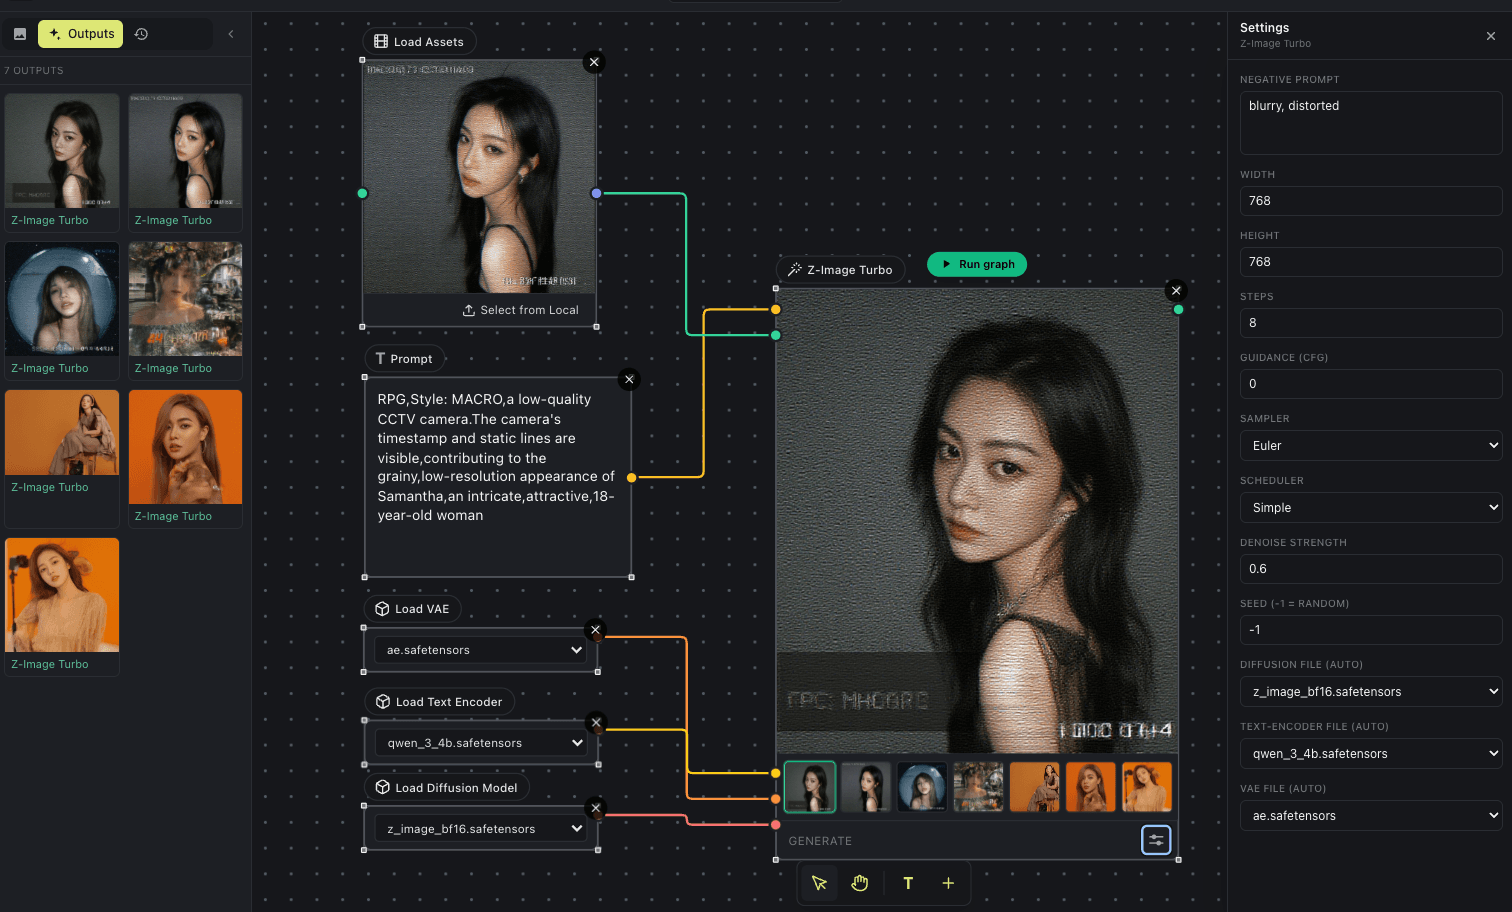
LoRA training
Your character, your style, your look
Keep a character consistent across shots, or lock in a custom visual style, by training your own model (a LoRA) right on the canvas. The Trainer tab turns a folder of images into a trained style without leaving the app. Wire Load Dataset into Caption into Train LoRA, watch the loss curve fall live, and the finished style saves straight to your models/loras folder, ready to drop onto the generation canvas.
- Load Dataset
- Caption
- Train LoRA
- Graph
- Resources
Per model: LTX-2.5 LoRA, Krea 2 LoRA, Z-Image LoRA, FLUX.2 LoRA, MiniMax H3 LoRA.
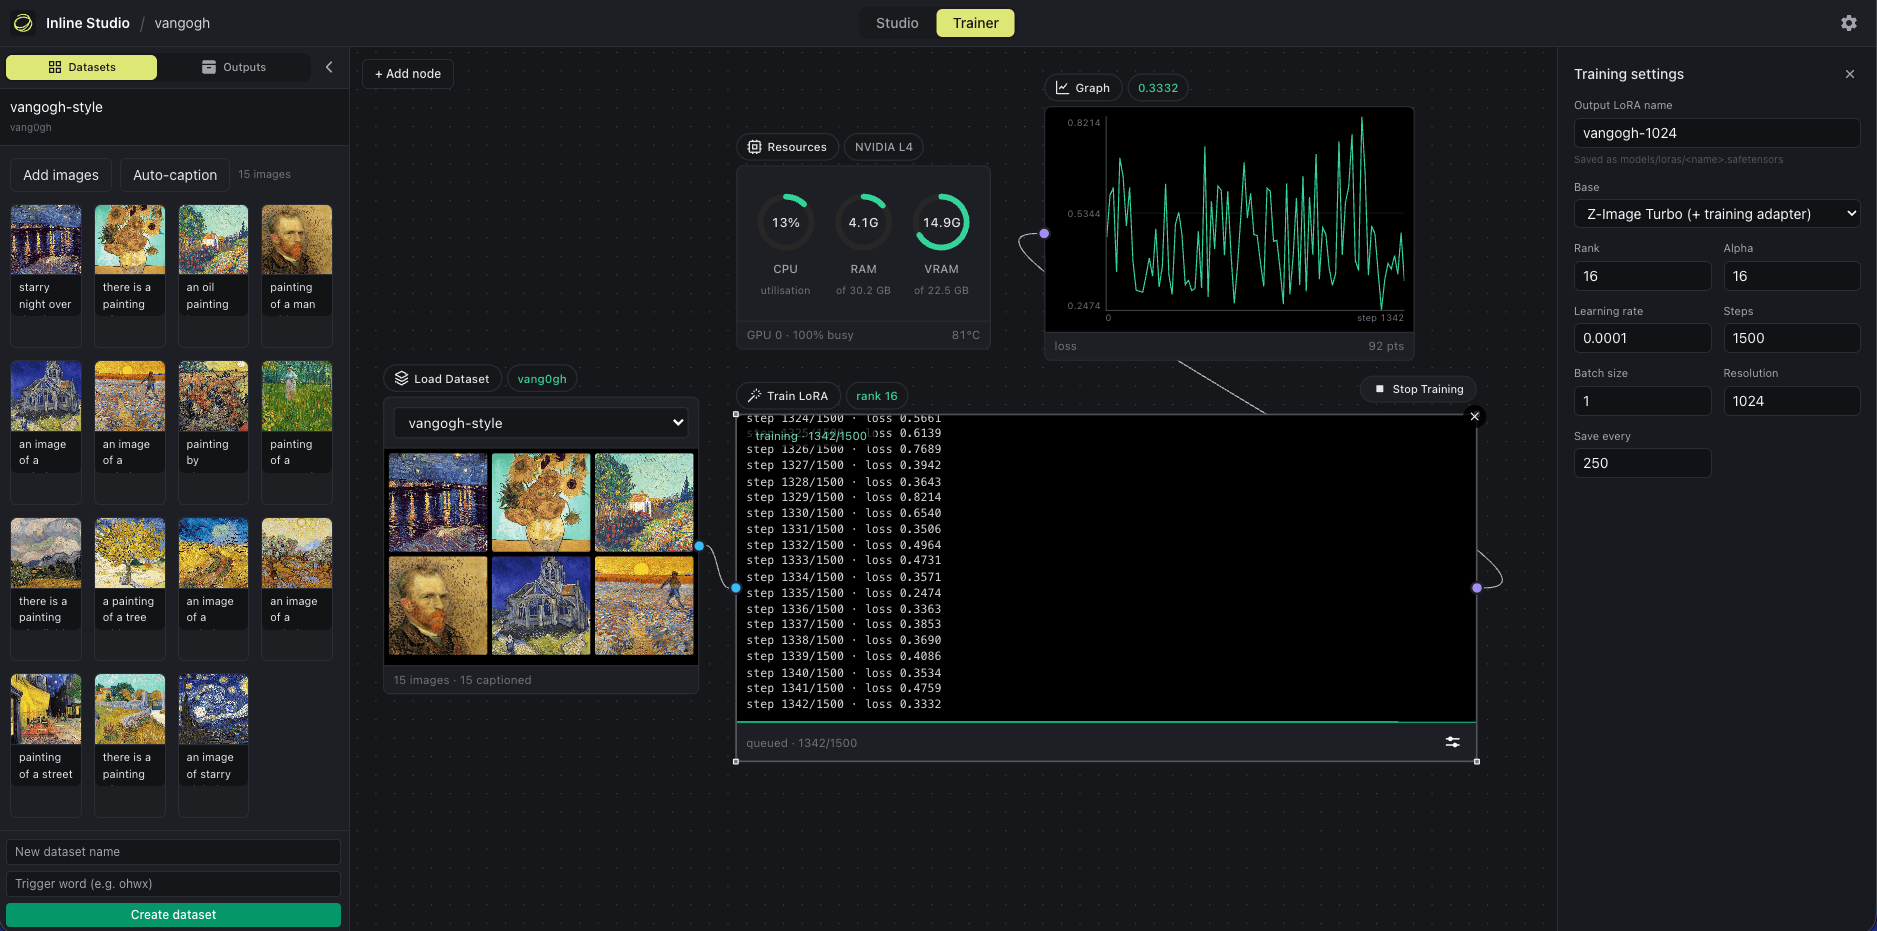
Training is just another graph
No scripts, no notebooks, no config files. Auto-caption a folder of images, wire the nodes, and hit Start. The Graph node plots loss step by step while a Resources monitor tracks CPU, RAM, and VRAM in real time.
Stop and resume, never restart
Stop a run and it flushes a checkpoint with the adapter weights, optimizer and RNG state, and step count all intact, so resuming picks up on the exact step you paused. Interrupted runs recover on their own.
Train on the base, generate on the fast one
Every architecture trains on an undistilled base, so the LoRA carries over to the distilled checkpoint unchanged. Set a trigger word and the finished file lands in models/loras, ready to prompt.
The three image models all train at 512px on a 16GB card, FLUX.2 in about 8.6GB. Measured peak VRAM for every model and card, and what each setting costs, is on the LoRA training guide.
Video, locally
Clips with sound, on your own GPU
Two open-weights video models run inside OmniChar, and both generate a soundtrack in the same pass as the picture. No account, no per-second billing, no queue. A take is one MP4 with sound in it, ready for the timeline.
LTX-2.5
Lightricks' 22B open-weights model, in three nodes: text to video, image to video, and first-and-last frame. Two modes on each one, a fast distilled pass and a guided quality pass. It streams its own weights, so a card that cannot hold the model runs it slowly rather than refusing it.
MiniMax H3
A 33B model in four nodes, including a reference node that takes up to nine images, three clips and three audio references and lets you address them by position in the prompt. 24 fps between 5 and 15 seconds at a 768 pixel short edge.
Both train LoRAs locally too, on clips rather than stills, so an adapter can carry motion and not just look. What that costs on a real card.
Hosted models, no GPU
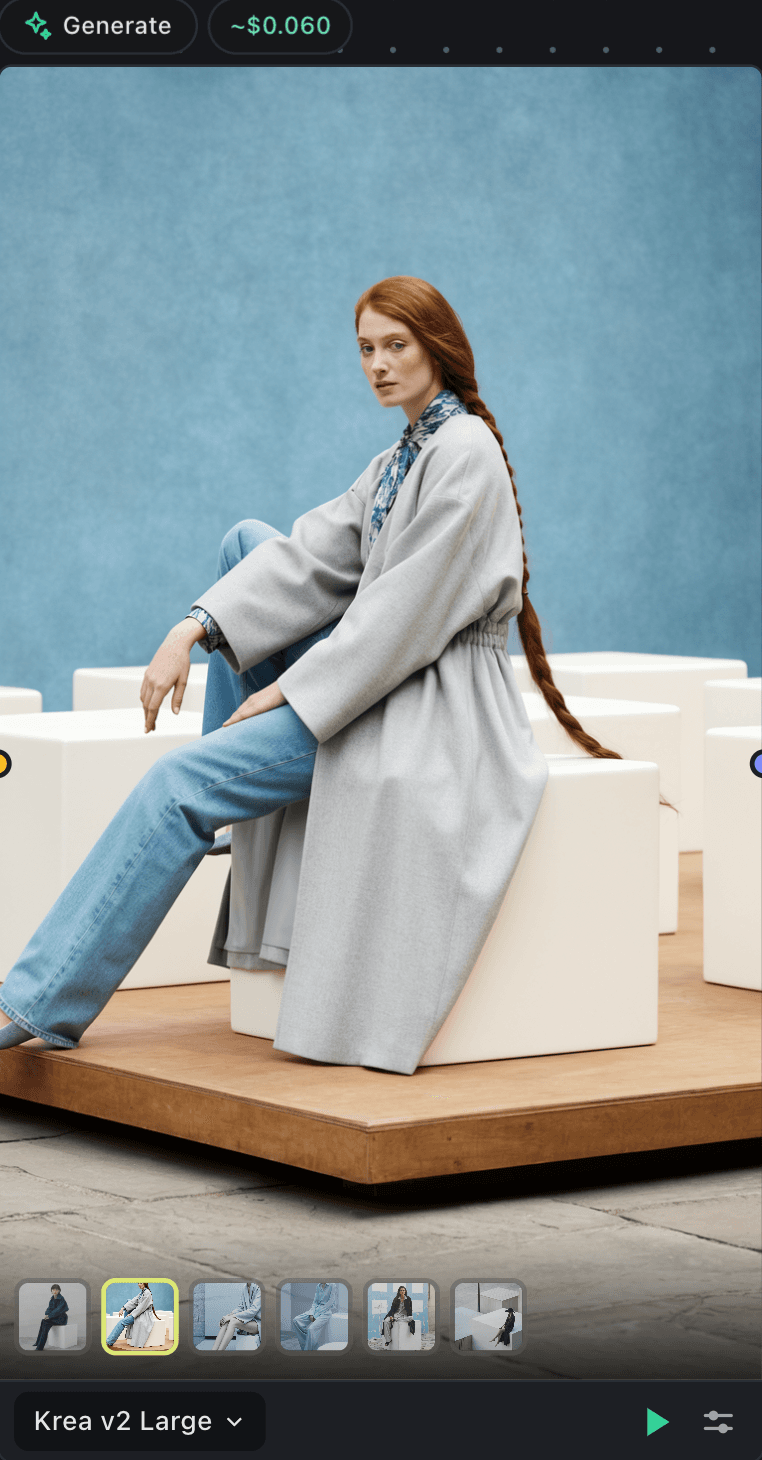
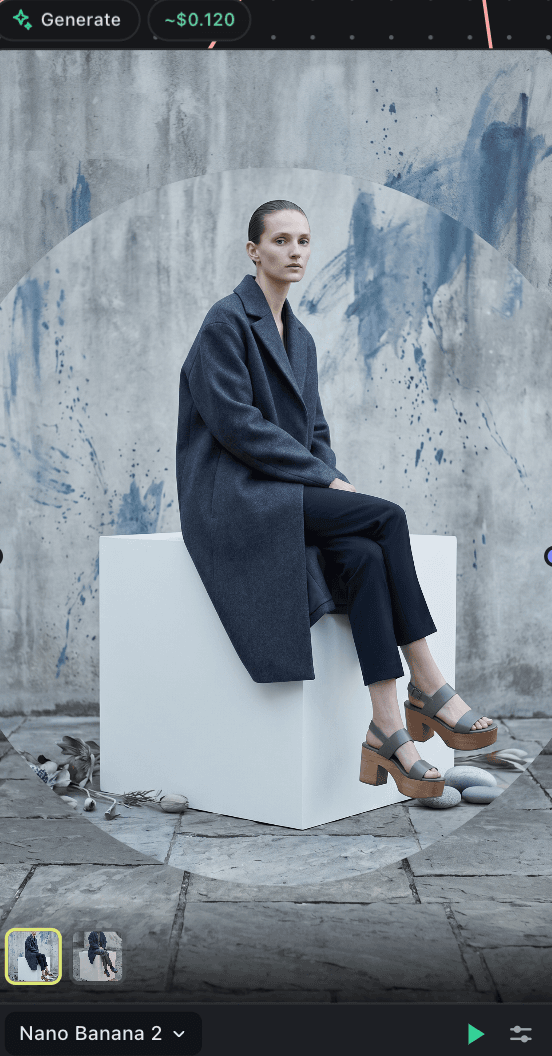
API Nodes bring hosted, closed models onto the same canvas, with no GPU and no setup. Add a Generate node, pick a model, and bring your own provider key. It stays on your machine, and you pay the provider per render, with a rough price estimate on every node before you run. Mix hosted models with your local renders in the same film.
- Image
- GPT Image 2, Nano Banana, Krea (hosted)
- Video
- LTX, Seedance
- Audio
- Sonilo
Install
Copy, paste, and it runs
One command sets up the engine, the model runtime, the trainer and the UI. On an NVIDIA machine it pulls the CUDA build of PyTorch for you.
- 01Python 3.11 or newer. No Node.
- 02NVIDIA on Linux or Windows is the tested path. CPU works, slowly.
- 03No downloads first. Grab checkpoints on first run.
- 04Leaves your other environments alone.
$ curl -LsSf https://astral.sh/uv/install.sh | sh$ git clone https://github.com/omnichar/OmniChar.git$ cd OmniChar/core$ ./webui.sh --install --extra all$ ./webui.shOn Windows use .\webui.bat in place of ./webui.sh, or just double-click it.
On an NVIDIA card the installer picks the CUDA build to match your GPU. If it gets that wrong, re-run with --torch-index cu130 and see the README's RTX 50-series section.
No GPU? Launch OmniChar on RunPod
Frequently asked questions
New to OmniChar? Read the getting-started guide →
What is a .char file?
A character file. Your reference photos are standardised once and stored with an SFace face signature and a DINOv2 subject signature, alongside any adapter trained from the same photos and a voice clip if you add one. That one file is the character, and it goes where you go: load it in OmniChar, in ComfyUI, or on hosted models such as Nano Banana Pro and MiniMax H3 Reference to Video. Every file records how it was made and who it belongs to.
Can I keep a character consistent across shots?
Yes, that is what OmniChar is for. Build the character once from a handful of your own photos and it stays itself from shot to shot: same face, same body, same wardrobe. You do not re-attach reference images or describe the face in the prompt again, and you do not rebuild anything when you change model.
Which models do characters work with?
FLUX.2, MiniMax H3 and Krea 2 locally, plus Nano Banana Pro and MiniMax H3 Reference to Video as hosted models. FLUX.2 and H3 Reference to Video read a character's references directly, so there is nothing to train, and H3 carries the voice too. Krea 2 and H3's other nodes have no reference channel, so the same photos become a LoRA trained on the same canvas. Seedance 2.0 rejects any reference with a face in it, so a character reaches it as build and wardrobe only.
Is OmniChar free?
The app is free and open source under the GPL-3.0 license. It runs on your own machine and nothing is metered. OmniChar Cloud is the hosted version for people without a GPU: 300 free credits to start, 3 credits an image at 1K, then you pay per generation.
Do I need a GPU?
Not for OmniChar Cloud, which runs the models on our GPUs and charges per generation. Locally a GPU makes generation much faster. Inline Core runs Z-Image Turbo, FLUX.2, Krea 2, MiniMax H3 and LTX-2.5 on your own card. FLUX.2, FLUX.1, Krea 2 and Z-Image Turbo train LoRAs on a 16GB card, MiniMax H3 does too but slowly, and LTX-2.5 wants 48GB.
What does OmniChar Cloud cost?
You pay per generation. New accounts get 300 free credits, an image at 1K costs 3 credits, and credits never expire. Top up from $10.
Can I use my characters in ComfyUI?
Yes. Install the OmniChar nodes, drop a Load Character node into a workflow you already use, pick a .char and wire it into your sampler. It works the other way too: a character built in ComfyUI opens in OmniChar's Characters panel.
Can I train my own LoRAs?
Yes, on your own images or short video clips, with no cloud step. The training nodes sit on the same canvas as everything else: wire Load Dataset into Caption into Train LoRA, press Start, and watch a live loss curve, with checkpoints you can stop and resume. The finished LoRA lands in your models/loras folder, where the LoRA loader picks it up straight away. Training needs a GPU, and the trainer comes with the --extra all install.
Can I get the pipeline back out of an image?
Yes. Every image OmniChar generates locally carries the graph that made it inside the PNG file. Drop that file back on the canvas and it offers to rebuild the pipeline: the nodes, the wiring, the prompt and the settings. Switching between a frame's earlier takes restores that take's prompt and settings too, so nothing you tried is lost.
Can I cut the finished video inside OmniChar?
Yes. The Video Director node is a timeline in a node: wire any number of frame outputs into it to build the video track, layer audio on top with per-input and per-layer volume, scrub the preview, and export the combined high-res video. A Trim Video/Audio node trims clips over their filmstrip or waveform before they reach the director.
Is there a desktop app to install?
No. OmniChar Cloud runs in a browser. Locally there is no installer either. You start one process from the source and it serves a web UI you open in your browser, which needs Python 3.11 or newer and uv.
Can I add my own nodes?
Yes. Install community extensions from the registry in one click, or paste any GitHub repo URL. Every install is security-reviewed, its dependencies are kept apart from the shared torch runtime, and the nodes appear on the canvas with no restart. You can build your own with the extension guide.